 Ruben Buijs
Customer support automation should remove repeat work without making customers fight for help. Start with work that follows clear rules, has a result you can check and can stop safely when something unusual happens.
The short answer: begin with approved answers, routing, read-only lookups and summaries. Add reversible actions after those work. Keep complaints, uncertain investigations and sensitive decisions with people, or put the action behind human approval.
You do not need to invent this order from scratch. Intercom's guidance starts with knowledge, handoffs and then workflows. Zendesk groups customer support automation around answers, routing, notifications, knowledge and repeatable workflows. Both point to the same practical rule: automate known work before uncertain decisions.
Start with the support work that is usually safe to automate
Most support teams can begin with the same four layers:
| Start here | What automation does | Keep controlled |
|---|---|---|
| Approved answers | Uses current policy, product or service information | Remove old or conflicting sources |
| Routing and tagging | Sends the request to the right team or workflow | Keep a fallback when no route matches |
| Read-only lookups | Finds an order, booking, account or delivery state | Verify identity and never expose another customer's data |
| Summaries and context | Prepares the request for a person | Preserve the original conversation as evidence |
These are good starting points because they do not need the AI to make a business decision. A customer either receives a supported answer, gets the correct data or reaches the right person with useful context.
The next layer is actions. Resending a tracking link is easy to reverse. Refunding money or changing access is not. Those actions should wait for approval until the team has seen enough real results to trust the workflow.
Zendesk's own workflow example shows the AI collecting structured customer information and changing the route based on business hours. That is a useful model for work that the AI can prepare but a person should finish.
The list gives you a starting point. Your own queue tells you which one is worth building first.
Use your queue to choose the first workflow
Nina leads support for an online store. She wants to automate order questions, but she does not yet know whether delivery answers, order lookups or replacement requests create the most repeat work.
Nina reviews a small set of recent conversations beside the teammate who handled them. For each one, she writes down what happened next: answered, routed, looked up, changed or investigated.
This is not research into what support automation could possibly do. The common starting points are already known. The queue check tells Nina which one appears often enough in her business to build first.
A request may contain an answer, a lookup and a decision, even when the customer wrote only one sentence.
| What the teammate does now | What automation can do | What must stay controlled |
|---|---|---|
| Copy a known answer | Answer from the sources your business trusts | Use only current, approved information |
| Forward the request to another team | Recognize the topic and route it | Keep a fallback when no team matches |
| Search for a customer, order or booking | Run a read-only lookup | Never reveal another customer's data |
| Update a field, resend a link or book a time | Run a repeatable action | Validate the input or require approval |
| Compare evidence or investigate an exception | Collect the context for a person | Let the person own the decision |
These are not five fixed workflows. One customer request can contain several rows. A delivery question may need a policy answer, an order lookup and a person when the parcel is missing.
The exact split changes by business. One store can answer delivery estimates from a webpage. Another needs a live warehouse lookup. Nina therefore checks her own queue instead of assuming every order question needs the same setup.
One conversation explains the method, but it does not show which work appears most often. Nina now repeats the exercise with 100 recent requests from different days and channels.
The rule: automate a complete support outcome, not a reply. A fast answer that creates another contact has moved work, not removed it.
For every request, Nina writes down what happened next: answered, routed, looked up, changed or investigated. She is not guessing the customer's intent. She is recording the work that actually followed.
She finds:
| Type of work | Requests | Example | First decision |
|---|---|---|---|
| Documented answer | 42 | "When will my order ship?" | Good first automation candidate |
| Read-only lookup | 24 | "Where is order 4812?" | Automate after the data source is connected |
| Reversible action | 14 | "Resend my tracking link" | Add after the lookup works |
| Judgment or investigation | 15 | "The carrier says delivered, but nothing arrived" | Keep human |
| Sensitive decision | 5 | "Refund this order" | Require approval |
The table does not say that 80 requests should disappear from the queue. It says 80 requests contain at least one repeatable step.
That difference matters. An order lookup can be automated even when a missing parcel still needs investigation. Nina can remove the search work without pretending the whole request is solved.
Choose one request with a result you can check
Nina starts with order-status questions because they occur often and have a clear result. The customer receives a status and tracking link, or an unusual delivery reaches a person.
One customer, Leila, asks:
"Where is order 4812? It should have arrived yesterday."
Leila is one example from that group. Nina creates the order-status workflow once, then the AI uses each customer's order number when it runs the same lookup.
The useful automated outcome is not "send a friendly answer." It is:
- Read the approved delivery policy
- Look up order 4812 and its latest carrier status
- Explain the result and share the tracking link
- Hand over when the order state needs investigation
That is one complete loop. It has an answer, an action and a boundary.
Before connecting software, Nina writes the expected result:
If status = in_transit and an estimate is available:
  explain the latest status and share the tracking link

If status = delivered but the customer has no parcel:
  do not guess
  pass the order, delivery scan and customer message to support
This small specification is more useful than a broad list of chatbot features. It tells the team what success and failure look like.
Now Nina knows the outcome she wants. She can connect only the information needed to produce it, instead of feeding the AI every document she can find.
Connect the sources the team already trusts
The workflow needs two sources:
- The delivery page that explains estimates and carrier scans
- The order system that holds the live status and tracking link
Nina does not rewrite all support material. She selects the shipping and delivery pages that answer this request. She also adds the support handbook PDF used by the team.
Add the relevant website pages and handbook to your AI Agent's knowledge. Test the exact question before adding an action. The answer should cite the source and stay inside the selected material.
If the answer is wrong, fix the source or add a Revised Answer. Do not hide a source problem behind a longer prompt.
The source test must pass before the lookup is added. Otherwise Nina will not know whether a bad answer came from the documentation or the account data.
Once the answer is reliable, the live order status is the only missing piece. That is where a read-only action earns its place.
Add the safest useful action
Next, Nina configures a read-only AI Action that accepts an order number and returns four fields:
{
  "status": "in_transit",
  "carrier": "PostNL",
  "estimated_delivery": "2026-10-11",
  "tracking_url": "https://tracking.example/4812"
}
Read-only work is a good first action because the AI can gather evidence without changing the account.
The action still needs a failure path. A timeout, missing order number or unexpected response should trigger a handoff. It should never produce a made-up delivery status.
Read the latest delivery state before answering
The mockup shows the three decisions Nina must verify: the action input, the fields it returns and what happens when it fails. If one is missing, the workflow is not ready.
The lookup can now find the facts. The next question is who may act on them when the request affects money, access or inventory.
Keep authority with the person who owns the risk
After the lookup works, it is tempting to automate the follow-up too. A missing parcel looks simple, but the right response depends on the carrier scan, the order value and the replacement policy.
Sending a replacement changes inventory and cost. Nina keeps that action behind human approval.
Use three control levels:
| Control | Use it for | Leila's workflow |
|---|---|---|
| Automatic | Read-only or easily reversible work | Read order status and share tracking |
| Human approval | A known action with customer impact | Resend an item |
| Human-owned | Uncertain cause or policy decision | Investigate a missing delivery |
Choose whether the action runs automatically, waits for approval or hands over. That choice should follow the risk of the action, not the confidence of the wording.
This is also where the human handoff design becomes part of automation. The handoff is not a backup after automation. It is one of the possible outcomes of the workflow.
When the action changes money, access or customer data, require human approval. Choose the team or person who owns that risk. The proposed input then waits in Inbox before it runs.
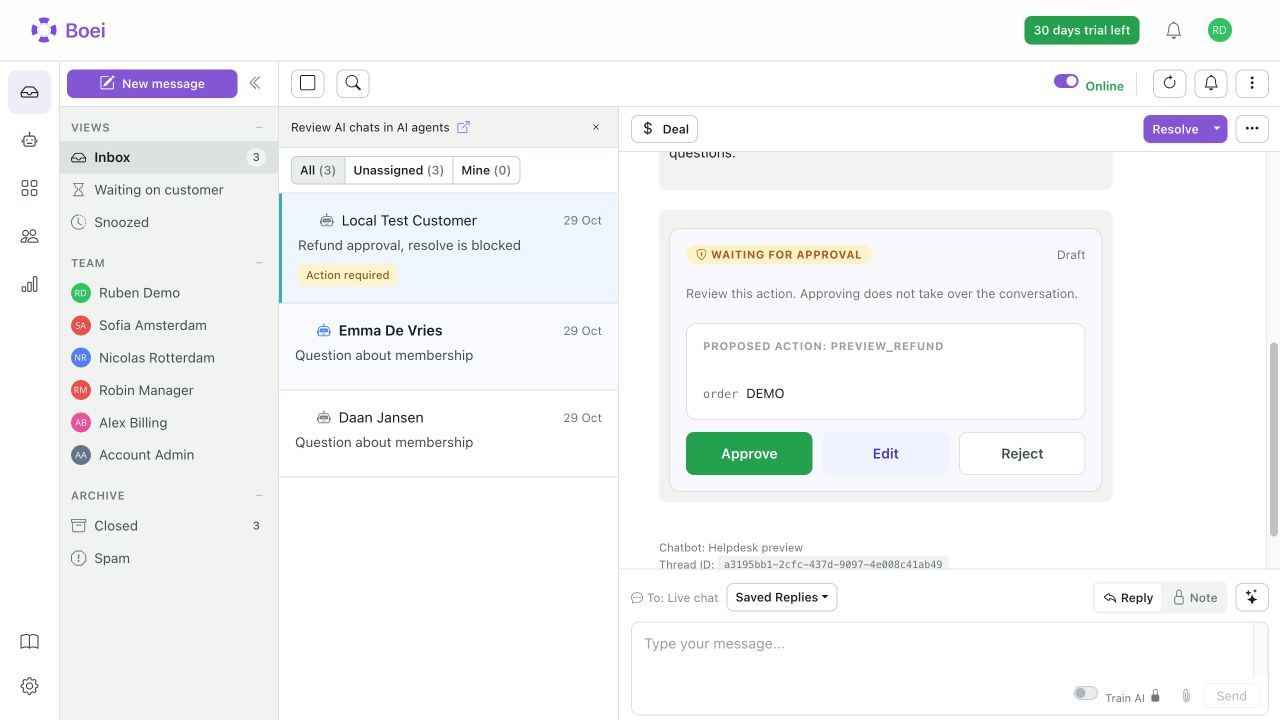
With the boundary in place, Nina can test the workflow without risking a real refund or replacement. The tests now need to cover more than the happy path.
Run the workflow against real variations
Nina tests ten anonymized versions of the request:
- An order that is still being packed
- An order in transit with a new estimate
- An order marked as delivered
- A customer who omits the order number
- A lookup that times out
- A carrier status the action does not recognize
- A customer who asks for a person immediately
- A customer who disputes the delivery scan
- A customer who asks two questions in one message
- Leila's overdue order
The happy path is only one test. The boundary tests reveal whether the workflow knows when to stop.
Nina can replay the same conversation herself by typing as the customer. Once the useful variations are clear, she saves them as a saved chatbot test. The same cases can then run again after a source, action or instruction changes.
Nina records four outcomes for each test:
- Correct answer
- Correct action result
- Correct handoff decision
- Useful context for the person
If a test fails, she changes one layer at a time. She fixes training for answer errors, action mapping for data errors and escalation rules for ownership errors.
Those tests prove that the workflow knows its limits. A narrow launch now shows whether it also removes work in real conversations.
Launch narrowly, then count returned work
The first workflow goes live only for order-status questions on website chat. Nina does not connect every channel or automate every order action.
After two weeks, she reviews the conversations. The AI handled 38 order-status questions. Twenty-six ended without another contact. Seven reached a person with the right context. Five needed correction because an old shipping page still promised a delivery window the carrier no longer used.
Start with the questions your AI Agent could not answer. Similar questions are grouped together, so Nina can see whether one missing source caused several failed conversations.
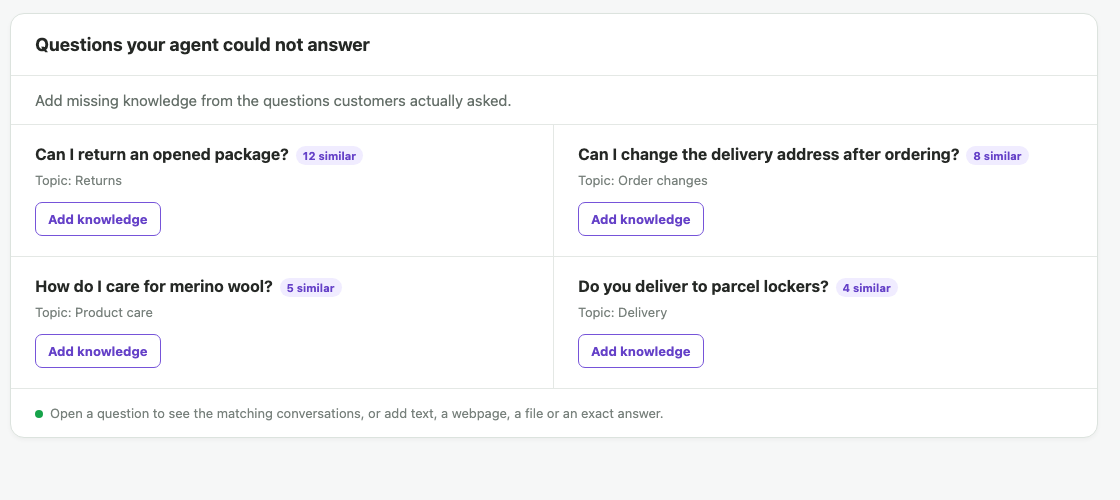
In this view, a missing returns answer affected twelve similar conversations. Adding one approved source fixes a repeated gap. It is more useful than rewriting twelve replies separately.
The headline resolution rate is:
26 resolved conversations / 38 order-status conversations = 68%That number is not enough. Nina also counts the work that returned:
5 corrected answers + 3 repeat contacts = 8 returned requestsThe stale page is the obvious fix. Review the three repeat contacts separately. Check whether the answer was unclear, the action result was incomplete or the customer could not find the next step.
When a request reaches a person, inspect it in Inbox. The customer profile, earlier messages, completed AI work, team and reply controls should be together. If the teammate must search another thread to understand the request, improve the handoff before adding more automation.
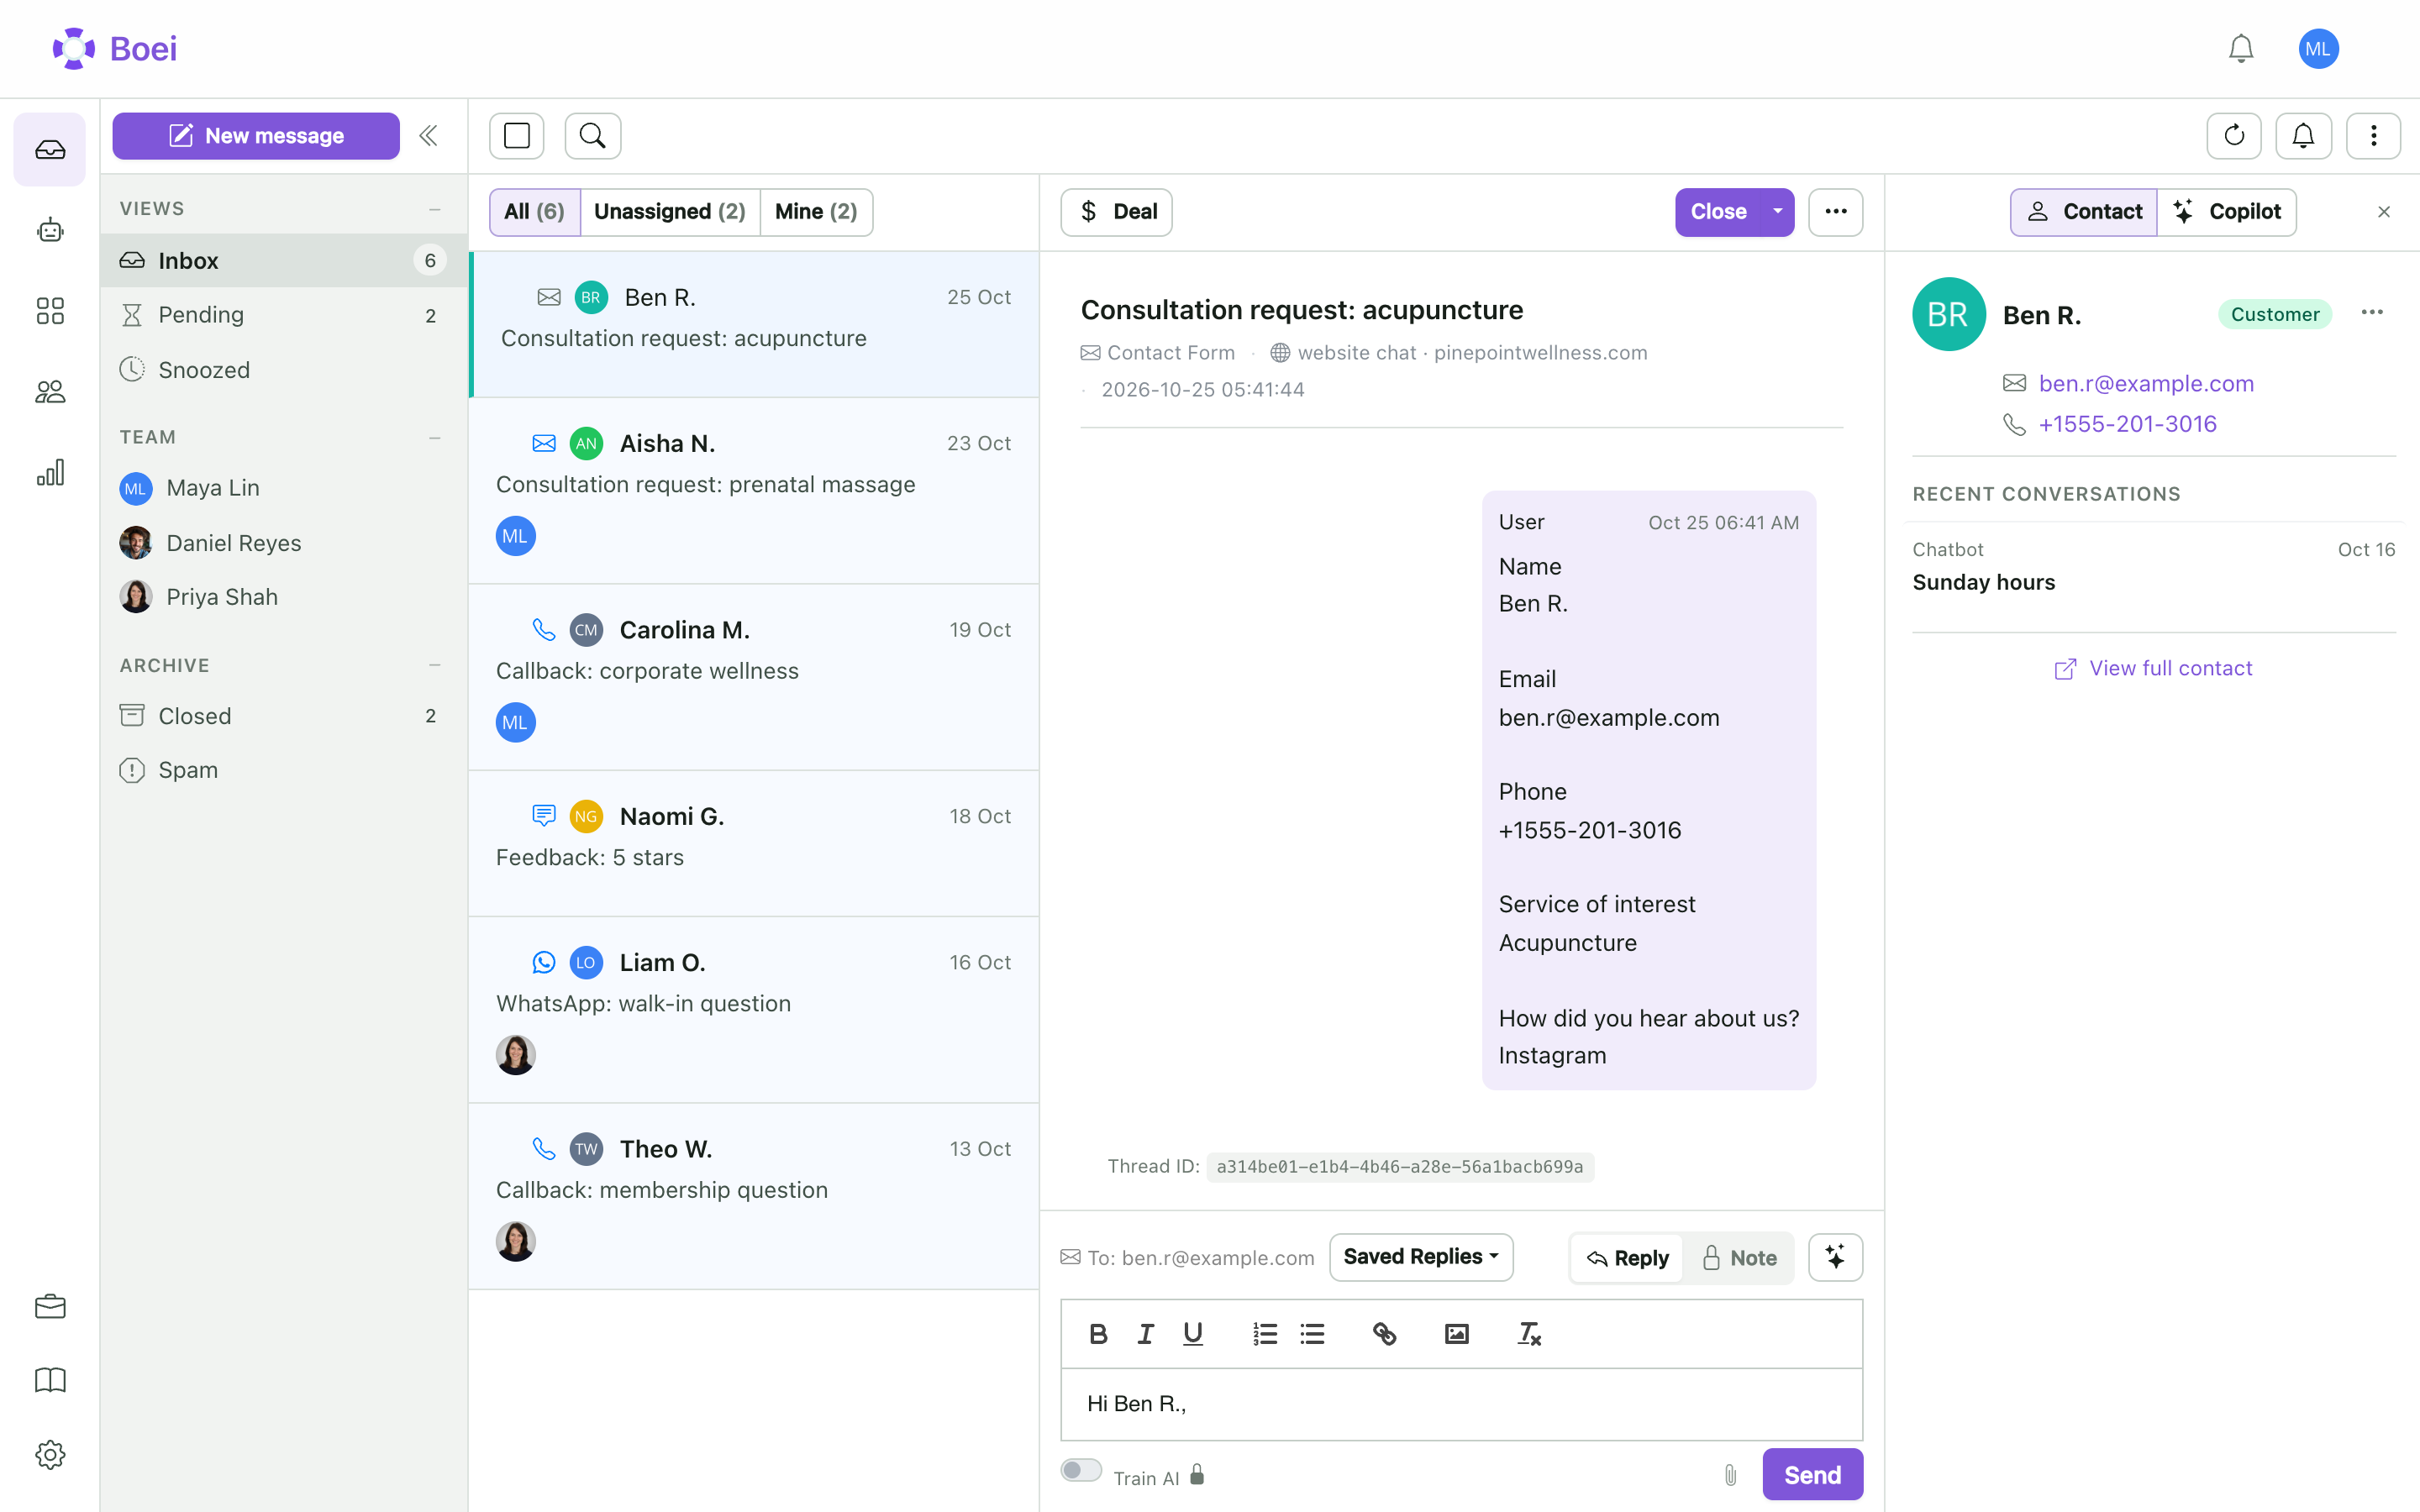
This is why automation rate should not lead the review. A chatbot can keep its handoff rate low by refusing to admit uncertainty.
Open AI Insights and track these measures together:
- Requests completed without another contact
- Corrections made by the team
- Repeat contacts about the same problem
- Failed or blocked actions
- Handoffs and their reasons
- Time a person still spends on the request
The support cost calculator can model a scenario before launch. Replace every assumption with measured data after the first workflow runs.
Use the result to choose the second workflow
Nina should not automate the next most common question automatically. She should inspect what the first workflow taught her.
The order lookup now works reliably. That makes "resend tracking link" a reasonable next candidate. It uses the same order number, carrier status and tracking data.
Refund decisions do not become safer because the order lookup succeeded. They need separate policy, approval and audit rules.
The next workflow should reuse proven parts without inheriting a false sense of safety.
This creates a practical sequence:
Approved answer
  -> read-only lookup
  -> reversible action
  -> approved account change
Move one step to the right only when the previous step works in real conversations.
The decision
Do not automate the biggest category or the easiest demo. Automate the smallest complete outcome that removes repeat work and exposes its own failure.
For Nina, that is not "AI customer support." It is a smaller promise: answer delivery questions and check order status. Disputed carrier states still go to a person with context.
Once that loop works, the team has evidence for the next decision. Until then, a larger automation roadmap is only a list of guesses.
Next step: Build the chosen workflow with the five-step AI helpdesk setup. Use one request from your own queue instead of Leila's example.
Frequently asked questions
What percentage of customer support should be automated?
There is no useful universal target. Measure the share completed correctly without repeat contact, then expand from the workflows that stay reliable.
What should we automate first?
Choose work that occurs often, uses a trusted source and has a result you can verify. Documented answers and read-only lookups are usually safer than account changes.
Should AI answer every support request first?
No. Let customers ask for a person. Route sensitive, urgent or clearly out-of-scope work directly to the team.
How do we know whether automation works?
Count completed requests, corrections, repeat contacts, failed actions and handoff reasons. A low handoff rate alone does not prove success.
Can an AI helpdesk run support actions?
Yes. Configured AI Actions can read data, calculate results and call APIs or webhooks. They can run automatically, wait for approval or trigger a handoff.